What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
GPU prices are a useful but incomplete bellwether for AI costs. They show what accelerator capacity may cost and can reveal changes in supply, demand and hardware generations. But an hourly rate alone cannot tell an IT leader what a training run or production AI service will cost. For budgeting, pair the rate with workload performance, expected utilization, availability, supporting infrastructure and operating costs.
What GPU prices tell you—and what they do not
GPU rental prices are a market signal: they can reflect accelerator supply, demand, data-center constraints, hardware generation and the premium for high-memory or tightly connected systems. A drop in rental rates for one model may indicate more supply or shifting demand; it does not prove that enterprise AI costs are falling. Teams may move to a newer accelerator with a higher hourly rate if it completes work faster or uses fewer GPUs.
GPU prices also do not directly predict hosted model API prices. An API provider can change its price through better batching, caching, model efficiency or fleet utilization, even if the price of renting GPUs moves in the opposite direction.
Historical market data illustrates why a single rate is a poor forecast. JPMorgan Asset Management’s December 1, 2025 review reported H100 rental rates of roughly $2 per hour at neoclouds, $7 at hyperscalers and $3.40 for AWS in its cited series, while AWS H200 pricing rose from about $3 to $3.30 per hour over the period covered. Those figures are historical context, not current universal quotes. JPMorgan Asset Management’s analysis also documents differing depreciation assumptions among large cloud and technology companies.
Recommended Free Tools
#1 Best Overall

- Powered by Radeon RX 9070 XT
- WINDFORCE Cooling System
- Hawk Fan
- Server-grade Thermal Conductive Gel
- RGB Lighting
Compare rates only after normalizing the unit
“GPU pricing” can mean several different things. A per-GPU-hour rate is not interchangeable with an instance-hour for a machine containing multiple GPUs, and neither necessarily represents the full cost of running a workload.
- Retail hardware price: the purchase price of a GPU or complete server.
- Cloud GPU-hour: a charge for an accelerator attached to a cloud machine; host resources or other services may be billed separately.
- Instance-hour: the price of a whole machine, which may include several GPUs. Divide by the GPU count only to get an arithmetic per-GPU figure, not to establish equivalent performance or configuration.
- Spot or preemptible: discounted capacity that can be interrupted and whose price or availability may vary.
- Reserved or committed: capacity or usage priced in exchange for a commitment, with a risk of paying for what goes unused.
- Capacity Block: scheduled access to a defined amount of accelerator capacity, with terms distinct from ordinary on-demand use.
- Managed inference: a provider operates the model and charges by tokens, requests or endpoint time, rather than exposing a simple GPU-hour price.
Google Cloud’s GPU pricing page separates GPU charges from some machine and related costs, and advises using its calculator for a complete estimate. Its published GPU rates vary by region and pricing arrangement. Google Cloud GPU pricing lists T4 at $0.35 per GPU-hour and V100 at $2.48 per GPU-hour in the cited list pricing; those figures are not a complete VM bill.
The following public prices were observed in August 2026. They are illustrative list or capacity rates, not guaranteed quotes; region, configuration, availability, taxes and billing terms can change the comparison.
| Provider and product | Observed rate | Unit and qualification |
|---|---|---|
| Lambda B200 SXM6 | $6.69 | Per GPU-hour; listed self-service rate; taxes may apply. |
| Lambda H100 SXM | $3.99 | Per GPU-hour; listed self-service rate, with host configuration. |
| Lambda A100 SXM | $2.79 | Per GPU-hour; listed self-service rate; suitability depends on workload. |
| AWS P6-B200 Capacity Block | $12.355 | Per accelerator-hour; eight B200 GPUs per instance; listed in several U.S. regions. |
| AWS P5 H100 Capacity Block | $5.191 | Per accelerator-hour; eight H100 GPUs per instance; listed in major U.S. regions. |
| Google Cloud T4 | $0.35 | Per GPU-hour; machine, storage and networking costs may be additional. |
| Google Cloud V100 | $2.48 | Per GPU-hour; regional list price, with commitments and spot priced differently. |
| CoreWeave A100 | $21.60 on demand; $9.51 spot | Per eight-GPU instance-hour; not directly comparable with per-GPU listings. |
See the providers’ Lambda instance rates, AWS Capacity Blocks pricing, Google Cloud GPU pricing and CoreWeave pricing for current details. AWS Capacity Block rates are reservation-based, not general on-demand prices. Google Cloud also publishes complete accelerator-optimized VM configurations separately: accelerator-optimized VM pricing.
Build a workload budget, not a GPU-hour budget
A GPU-hour estimate becomes useful only when it is attached to a defined job or service and expanded to include the rest of the bill. A practical infrastructure model is:
Total AI infrastructure cost = accelerator cost + host CPU and RAM + storage + data transfer and egress + networking + orchestration and observability + software licenses + engineering and operations + failed-job and retry cost + unused commitment cost.
Rank #2

- Powered by the NVIDIA Blackwell architecture and DLSS 4
- Powered by GeForce RTX 5070 Ti
- Integrated with 16GB GDDR7 256bit memory interface
- PCIe 5.0
- WINDFORCE cooling system
For a training run, begin with:
Training compute cost = number of GPUs × elapsed training hours × effective GPU-hour price × retry and utilization adjustment.
The effective rate should reflect discounts but also idle time, failed runs, queueing and reservation capacity that went unused. For inference, use the serving-period total rather than a theoretical fully occupied accelerator:
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Repair Windows errors before they cause bigger problems3Fix the driver behind crashes, sound loss and screen glitchesEffective cost per output token = total serving cost during the measurement period ÷ output tokens delivered during that period.
For comparing hardware or providers on throughput, express the result in useful output rather than hourly price:
Cost per million output tokens = hourly system cost ÷ output tokens delivered per hour × 1,000,000.
For training, compare the complete cost per successfully completed run, including storage, data movement and recovery after failed runs. Measure the workload on the target model and software stack: advertised accelerator specifications cannot tell you the realized tokens per second or training time.
Free tools Windows power users keep installed
One-click scans. No signup required.
Rank #3

- AI Performance: 767 AI TOPS
- OC mode: 2632 MHz (OC mode)/ 2602 MHz (Default mode)
- Powered by the NVIDIA Blackwell architecture and DLSS 4
- Axial-tech fan design features a smaller fan hub that facilitates longer blades and a barrier ring that increases downward air pressure
- A 2.5-slot design maximizes compatibility and cooling efficiency for superior performance in small chassis
Utilization can outweigh the hourly rate
A less expensive GPU can cost more per useful unit of work if it is idle much of the time, slower for the target model, memory-constrained or difficult to obtain when needed. Conversely, a higher hourly rate can pay off if better throughput reduces the number of accelerator-hours required.
A 2026 study of LLM infrastructure cost estimation found that, on identical H100 hardware, estimated effective cost ranged from $0.21 to $15.25 per million output tokens across different enterprise traffic conditions. It attributed much of the spread to utilization and concurrency, reporting underutilization penalties of 2.5× to 24× under low-to-moderate loads and up to 36.3× near idle. These are study results under its modeled conditions, not a universal cost range. The study and its assumptions are useful context for why a per-token estimate based on full utilization can mislead.
Workload shape changes what utilization is realistic:
- Training: Jobs can keep GPUs busy while running, but are often episodic and may be sensitive to interruption or scheduling delay.
- Batch inference: Queues and batching can raise utilization when latency is flexible.
- Interactive inference: Low-latency requirements and quiet periods can leave provisioned GPUs underused.
- Internal copilots: Traffic may be unpredictable, with low average concurrency but sharp peaks.
- Fine-tuning: Episodic demand may not justify ownership or a long commitment.
Before approving an estimate, collect GPU duty cycle, memory and tensor-core utilization, requests per second, batch size, tokens per second, queue time, model-loading time, failed and retried jobs, and both average and peak demand. Low average utilization and high peak demand create a different budget problem from steady, high-volume service.
Quick wins for a faster PC:
Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Repair Windows errors before they cause bigger problemsFix Now →Use annualized rates as a ceiling, not a forecast
Multiplying a rate by 8,760 hours shows what continuous use would cost for one year before non-GPU charges. Using the August 2026 examples, that arithmetic is about $34,952 for one Lambda H100 at $3.99 per GPU-hour, $45,473 for one AWS H100 Capacity Block accelerator at $5.191 per hour, $58,604 for one Lambda B200 at $6.69 per hour and $108,229 for one AWS B200 Capacity Block accelerator at $12.355 per hour.
These annualized amounts assume continuous occupancy and unchanged rates; they are not realistic annual budgets or forecasts. Multiply by the planned GPU count, then model actual scheduled hours and effective utilization. Add host, storage, network, operational and commitment costs separately. A reservation sized for peak demand can be wasteful if the peak occurs only briefly.
Rank #4

- Powered by the NVIDIA Blackwell architecture and DLSS 4. System Requirements: Minimum 850W PSU with 16-pin 12V-2x6 (12VHPWR) connector required. Verify before purchasing.
- Military-grade components deliver rock-solid power and longer lifespan for ultimate durability. Compatibility: 348mm (13.7") length, 3.6 slots, 4.3 lbs. Confirm case clearance and slot spacing. GPU bracket included.
- Protective PCB coating helps protect against short circuits caused by moisture, dust, or debris
- 3.6-slot design with massive fin array optimized for airflow from three Axial-tech fans
- Phase-change GPU thermal pad helps ensure optimal thermal performance and longevity, outlasting traditional thermal paste for graphics cards under heavy loads
Choose the purchase model around workload certainty
| Pricing model | Useful starting point | Main budget risk |
|---|---|---|
| On-demand | Prototypes, short experiments and uncertain demand. | Higher apparent rates, possible capacity gaps and costs that grow without governance. |
| Reserved or committed | Predictable sustained use, repeated training or production inference. | Paying for unused capacity; provider, region or hardware lock-in. |
| Spot or preemptible | Checkpointed training, batch inference, sweeps and non-urgent jobs. | Interruption, scarcity, variable price and restart engineering. |
| Capacity Block | Scheduled training that needs a defined accelerator window without a long-term reservation. | Booking constraints and a reservation fee that must be justified by actual use. |
On-demand for uncertain use
On-demand capacity is a sensible way to price experiments when neither workload size nor schedule is established. Do not treat a listed rate as proof that a particular GPU or cluster will be available in the required region at the required time.
Commit only against a utilization profile
A commitment can reduce unit rates for steady demand, but the relevant comparison is total committed spend against what the workload will actually consume. Google Cloud documents one- and three-year commitments for eligible GPUs and notes that GPU resources may require reservations for resource-based committed-use discounts. Its pricing page also distinguishes those arrangements from spot rates.
Use spot only when recovery is economical
Google Cloud says spot pricing is dynamic and can offer 60% to 91% discounts for many machine types and GPUs, with smaller discounts for some configurations, including A3. That range is not a guaranteed discount for every GPU, location or time. Model interruption frequency, checkpoint cost, restart time and the cost of delay before counting a spot saving.
Reserve a defined window for scheduled work
AWS describes Capacity Blocks for ML as scheduled accelerator reservations with an upfront reservation fee and operating-system fee. AWS says prices are updated based on supply and demand and the charged price is the prevailing rate when the reservation is purchased. Check the current terms and ensure the job can use the booked window before treating this as cheaper than on-demand capacity. AWS Capacity Blocks pricing and terms provide the current details.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Compare GPU generations by completed work
Hourly prices do not establish which accelerator is economical. Compare memory capacity, bandwidth, precision support, throughput on the intended model, cluster scaling, energy use and software compatibility. A newer GPU may cost more per hour yet finish a training run faster, serve more tokens per hour or reduce the number of GPUs needed. An older A100 may still be a good fit for some development, inference or batch workloads; it is not automatically obsolete.
Lenovo’s 2026 comparison reports more than a threefold throughput improvement between Hopper and Blackwell for the same model in its tested comparison. That result depends on the tested configuration and workload, so it should motivate a benchmark of the intended stack rather than be used as a universal multiplier. Lenovo’s comparison also illustrates how cloud rates change with generation and commitment term.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Best Value
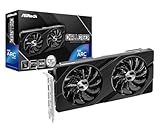
- Next-Gen Intel Arc Graphics: Powered by Intel Arc A580 GPU with Intel Xe HPG microarchitecture, featuring 384 XMX engines for enhanced AI acceleration and content creation.
- High-Performance Memory: 8GB GDDR6 on a 256-bit interface running at 16 Gbps, delivering excellent bandwidth for 1440p gaming and creative workloads.
- Factory Overclocked: Engine clock set at 2000 MHz out of the box, providing optimized performance for smooth gameplay and multimedia tasks.
- Advanced Dual-Fan Cooling: Features a dual-fan design with striped axial fans and an ultra-fit heatpipe for efficient thermal management. 0dB Silent Cooling stops fans completely at low temperatures for silent operation.
- Durable Construction: Includes a stylish metal backplate for enhanced PCB rigidity and a premium aesthetic, backed by ASRock's Super Alloy components for long-term reliability.
Memory is a hard constraint: a cheaper accelerator may not fit a model that needs more memory unless the team uses quantization, sharding or offloading. Those workarounds can add engineering effort and reduce performance. A single GPU is also not a substitute for an interconnected multi-GPU node when the job depends on high-bandwidth communication.
Decide whether to rent, buy or avoid owning GPUs
Cloud rental is generally easier to justify for experimental, seasonal or uncertain demand, immediate bursts, teams without specialist operations staff, or workloads at risk of becoming inefficient on older hardware. On-premises ownership merits a full cost model when utilization is expected to be consistently high, demand is predictable, financing is available, facilities and power exist, data requirements favor local infrastructure, and the organization can operate the system.
An ownership calculation must include the server, networking, racks, power distribution, cooling, space, electricity, support, spares, staffing, security, software, financing, depreciation, residual value and the risk that models or workloads change. Compare cost per useful unit of work over a realistic utilization profile—not server capital cost against a cloud hourly rate.
Lenovo’s 2026 vendor-sponsored analysis offers one scenario, not a general price benchmark: it models an eight-H200 on-premises system at about $397,802 and Azure rates of approximately $114.65 per hour on demand, $73.39 for a one-year reservation, $50.33 for three years and $46.56 for five years. Its example estimates roughly 9,800 hours to break even against the three-year reserved comparison. Treat that result as dependent on its hardware, pricing and operating assumptions; test electricity, labor, utilization, financing, warranty, cloud discount and residual-value assumptions for your own case. The analysis describes its scenario.
Separate three different concepts in an ownership model: accounting depreciation, physical service life and economic useful life. JPMorgan Asset Management’s review of company filings cited 2025 depreciation assumptions of five years for Meta and Amazon and six years for Google, Oracle and Microsoft. Those accounting lives do not establish how long a particular GPU remains economically competitive. Memory limits, energy use, throughput, cluster compatibility and software support can make a functioning GPU uneconomic sooner; alternatively, older hardware may remain useful for less demanding work. JPMorgan’s review provides the filing context.
Include capacity and alternatives in the decision
A public price is not a usable budget input if the required GPU is unavailable in the needed region or cluster size. Check regional capacity, multi-GPU topology, interconnect requirements, scheduling delay, minimum rental duration, data proximity, compliance requirements and provider reliability. Google Cloud notes that GPU availability is specific to regions and zones; verify locations before planning a deployment. Google Cloud’s GPU pricing page links to location details.
There may be no need to own or rent a GPU for every AI workload. Compare self-hosting with managed model APIs, serverless endpoints, CPU inference for small or optimized models, a smaller model, quantization, distillation, retrieval-augmented generation, batch processing, shared internal GPU pools, or outsourcing training and fine-tuning. Specialized accelerators such as TPUs or AMD GPUs may be alternatives when the software stack and model are compatible. For low or unpredictable traffic, a managed API can be easier to budget; compare its actual per-token price and service terms with the fully loaded self-hosted cost.
Stress-test the budget before approval
Build low, base and high cases rather than relying on one utilization estimate or one provider quote. Vary the assumptions that can change the result materially:
Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteWindows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstall- Workload type, model, input/output token mix and latency target.
- GPU model, memory, GPU count, node topology and interconnect.
- Measured throughput, expected hours, average and peak utilization, and queueing.
- Region, currency, price date, taxes and actual capacity availability.
- On-demand, spot, reserved or Capacity Block terms, including unused hours.
- Storage, data transfer, egress, networking, host resources and orchestration.
- Failed runs, interruption, checkpointing, retries and recovery time.
- Staffing, facilities, power, cooling, financing, depreciation and residual value for owned systems.
- Model-efficiency improvements, migration options and an exit plan if demand or hardware needs change.
For a provider comparison, record the price unit and configuration first, then benchmark the target workload and calculate cost per completed training run or delivered output token. Use a utilization distribution—not just a peak forecast—and verify availability before committing. This produces a budget that can be updated when rates, hardware or workload assumptions change.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




