OpenInfer announced an oversubscribed seed round of more than $8 million on February 20, 2025, generally reported as an $8 million financing. Cota Capital and Essence VC led the round. The company is building software to run AI inference across different kinds of hardware and deployment environments—from edge devices to private data centers and cloud systems. The financing is a concrete vote of investor interest in inference infrastructure, not proof that OpenInfer’s product is faster, cheaper, or widely adopted.
What OpenInfer raised—and who backed it
VentureBeat reported the seed financing on February 20, 2025, as an $8 million round. OpenInfer and investor MFV Partners described it as an oversubscribed round of more than $8 million, so “$8 million” is the common reported figure, while the company and investor wording indicates the total exceeded that amount. VentureBeat’s announcement and MFV Partners’ account identify Cota Capital and Essence VC as the co-leads.
Other named participants included B5 Capital, MFV Partners, Brave Capital, Future Fund, Machine Ventures, Pretiosum, SilverCircle, StemAI, Tau Ventures, YG Ventures, and others. Notable individual backers cited in the coverage included Jeff Dean, then chief scientist at Google DeepMind; Aparna Chennapragada, then Microsoft’s Experiences and Devices chief product officer; Oculus VR co-founder and former CEO Brendan Iribe; Gokul Rajaram; and Baris Aksoy. These names indicate investor interest, but do not establish customer adoption, technical performance, or likely investment returns. Public materials cited here do not establish the round’s valuation, terms, ownership stakes, or a more precise total.
Who founded the company
VentureBeat identifies Behnam Bastani and Reza Nourai as OpenInfer’s founders and reports that they spent nearly a decade building and scaling AI systems at Meta’s Reality Labs and Roblox. That systems experience is relevant to infrastructure software, but experience at large technology companies is not independent validation that OpenInfer’s own product outperforms alternatives. A company update published in April 2026 says OpenInfer launched in late 2024; that later timeline should not be confused with the date of the seed announcement. OpenInfer’s April 2026 update also said the company had 13 people, hired Kam Eshghi as chief revenue officer, and was discussing a potential Series A. It does not establish that a Series A had closed.
The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →#1 Best Overall
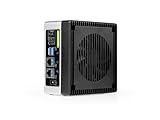
- Supercharged AI Performance: Powered by NVIDIA Jetson Orin NX 16GB, delivers up to 157 TOPS in MAXN Super Mode — ideal for vision AI, robotics, autonomous machines, and generative AI workloads.
- Advanced Thermal Engineering for Full-Power Operation: Equipped with a vacuum copper heat pipe system, ultra-low thermal resistance medium, and high-emissivity black-coated surface combined with high-performance active cooling — ensuring stable full compute power even at 60°C ambient temperature.
- Energy-Efficient & Flexible Power Modes: Adjustable power profile from 10W to 40W, enabling a perfect balance between performance and efficiency for edge AI computing in diverse environments.
- Industrial-Grade Reliability & Design: Ruggedized for operation from -20°C to 60°C at 40W (up to 65°C at 25W), providing dependable performance in industrial automation and outdoor AI deployments.
- Rich Connectivity & AI-Ready Platform: Features 2×RJ45, SIM slot, 4×USB 3.2, HDMI 2.1, CAN, M.2 Key E/M, Mini-PCIe, and 4×CSI camera ports — supporting multi-camera vision, IoT, and robotics projects. Pre-installed with JetPack 6.2 and 128GB NVMe SSD, fully compatible with NVIDIA Isaac, ROS 1/2, and Hugging Face frameworks.
What edge inference means—and why buyers care
Inference is the use of a trained AI model to produce an output, such as a classification, prediction, or generated response. In edge inference, some or all of that computation takes place near the user or the data source instead of sending each request to a centralized cloud service. “Edge” is not one particular device: it can mean a phone, a robot, an industrial computer, an edge server, or an enterprise’s private infrastructure.
- Latency: Local processing can avoid a round trip to a distant service, which may matter for interactive or time-sensitive systems.
- Privacy and control: Keeping data on a device or inside an organization’s network can reduce the need to send it to a third-party service. It does not remove the need for access controls, patching, encryption, and secure updates.
- Resilience: A local system may continue operating when connectivity is unreliable, depending on its design and whether it relies on remote services for other functions.
- Data-transfer costs: Processing data locally can reduce the amount sent over a network, but that does not automatically lower total cost.
The trade-offs are substantial. Edge hardware usually has less memory and compute than a large cloud GPU cluster; phones, vehicles, and embedded systems also face power and thermal limits. Large models may need quantization, partitioning, caching, reduced context lengths, or multiple devices. Local deployments add costs for hardware, engineering, monitoring, fleet management, upgrades, and maintenance. Cloud services, by contrast, offer elastic capacity and reduce the customer’s hardware-operating burden. A hybrid design—keeping sensitive or latency-critical work local and sending bursty or less sensitive workloads to the cloud—may suit some systems better than either extreme.
MFV Partners framed the opportunity around always-on inference in smartphones, wearables, autonomous vehicles, robots, healthcare, automotive, and manufacturing. Those are potential applications, not evidence that OpenInfer has deployments in each sector. The broader case for inference software is that trained models must be served repeatedly, and that serving across varied chips, models, and operating environments can be operationally difficult. A layer that makes those deployments easier could be valuable if it delivers measurable results without forcing customers to rewrite applications.
What OpenInfer says its software does
In the 2025 funding coverage, OpenInfer was described as an inference engine intended to run large models across different hardware, from system-on-chips to cloud infrastructure. The pitch was to avoid rewriting an application for every platform. MFV Partners described an approach involving quantized-value handling, caching, memory access, and model-specific tuning, and said an endpoint could be replaced by changing a URL. Those are investor and company descriptions of the product approach, not an independent compatibility or performance test. MFV Partners’ explanation also cited claimed speed comparisons with Ollama and llama.cpp; the available account does not establish enough common test conditions to treat those comparisons as general results.
By August 2026, OpenInfer’s site presented a broader “Inference OS” positioning: a software layer for running AI across CPUs, GPUs, NPUs and other accelerators, private data centers, edge servers, factory floors, air-gapped facilities, cloud environments, and hybrid deployments. Its described stack includes an application and API layer, request routing, an inference engine, memory and compute scheduling, kernels, and network coordination. The company also describes Loom and Weave concepts for orchestration. “Inference OS” is OpenInfer’s product positioning, not an established industry category. The company’s current site should be read as a description of its later offering, not a feature list for the product at the time of the 2025 seed round.
Rank #2

- AI-POWERED PRODUCTIVITY & MOBILITY - Experience next-generation computing with the Samsung Galaxy Book4 Edge, featuring a Qualcomm Hexagon NPU with up to 45 TOPS of AI performance to accelerate on-device AI experiences and unlock powerful Copilot+ PC capabilities. Designed to simplify everyday tasks and enhance productivity, it combines intelligent performance with up to 28 hours of battery life in a slim, lightweight design, making it an ideal companion for work, study, travel, and everyday use.
- POWERFUL PERFORMANCE - Powered by the Qualcomm Snapdragon X processor and integrated Qualcomm Adreno graphics, the Samsung Galaxy Book4 Edge handles everyday productivity, streaming, and entertainment with ease. Equipped with 16GB LPDDR5X 8448MHz RAM and 512GB UFS storage, it keeps apps and browser tabs running smoothly while providing ample space for files, apps, and everyday essentials.
- EXCELLENT VISUAL - Enjoy stunning visuals on the 15.6" FHD (1920 x 1080) IPS Anti-glare LED display with 300-nit brightness. USB4 and HDMI support two external 4K monitors @60Hz (without docking station). The enhanced 1080p FHD camera delivers clear, detailed video, while Windows Studio Effects, including background blur and automatic framing, help you look professional during video calls and virtual meetings.
- VERSATILE CONNECTIVITY - Equipped with two USB-C (USB4) ports, USB-A, HDMI, and a 3.5mm audio combo jack for seamless compatibility with monitors, docks, and essential peripherals. Wi-Fi 7 and Bluetooth 5.4 deliver fast, reliable wireless connectivity to keep you productive wherever you work. A full-size keyboard with a dedicated numeric keypad boosts productivity.
- OPERATING SYSTEM - Windows 11 Home provides built-in Copilot AI to help simplify everyday tasks, organize information, and enhance productivity. Built-in security features help protect your device and data, while an intuitive, user-friendly experience makes it easy to work, study, create, and stay connected throughout the day.
OpenInfer’s March 2026 Weave whitepaper describes execution strategy as a first-class choice, with sessions routed according to service-level requirements, context size, and available resources. Its four listed strategies are:
| Strategy | Intended use | Hardware described |
|---|---|---|
| Standard prefill | Latency-sensitive prompt processing | Single node, GPU or multi-GPU |
| Pipeline-parallel prefill | Throughput-tolerant batch prefill | Multi-node CPU/GPU mix |
| Standard decode | Interactive sessions | Single node, GPU or multi-GPU |
| Q-Ring decode | Throughput-tolerant workloads with large or aggregate contexts | Multi-node ring |
These are architectural descriptions in OpenInfer’s Weave whitepaper; they do not by themselves show which configurations are generally available or how they perform in independent tests.
What the seed money was meant to fund
OpenInfer said the financing would support expansion of its inference engine, hardware-vendor partnerships, a developer ecosystem, and broader deployment across devices and platforms. The company’s funding announcement records those plans; they should not be treated as verified milestones merely because they were stated as uses of proceeds. The later April 2026 company update provides evidence of hiring and go-to-market activity, but its description of a potential Series A is not evidence of a completed financing.
Do these 3 things before closing this tab:
1Clear out junk files and repair common Windows errors2Fix the driver behind crashes, sound loss and screen glitches3Repair Windows errors before they cause bigger problemsWhat the performance claims do—and do not—show
OpenInfer’s site, as available in August 2026, reported 2.5–4 times the throughput of a vLLM baseline, a comparison of 255.2 to 641.4 tokens per second, GPU utilization rising from 21.5% to 43.5%, and p95 latency falling from 508 ms to 268 ms for Qwen3.5-27B. These are first-party benchmark claims, not independently established results or guarantees. The figures should not be generalized beyond the company’s stated comparison: buyers need the hardware, model settings, batch and concurrency levels, latency target, and measurement method to judge whether they apply to their workloads. Tokens per second alone do not capture time to first token, tail latency, power use, reliability, or output quality.
The company also says it has deployed more than one trillion tokens in production and that some deployments have reduced costs to one-tenth. Both are company claims; the available public material does not provide enough customer or deployment detail to establish how broadly they apply. “Hardware agnostic” likewise needs a supported-hardware list and configuration-specific evidence: software that supports multiple vendors is not necessarily optimized equally for every chip. OpenInfer describes cloud, on-premises, and edge options, including OpenInfer Cloud, so a claim of no cloud dependency applies only to relevant deployment modes, not to every product configuration.
Rank #3

- The NVIDIA Jetson AGX Orin 64GB Developer Kit makes it easy to get started with Jetson Orin. Compact size, lots of connectors, and up to 275 TOPS of AI performance make this developer kit perfect for prototyping advanced AI-powered robots and other autonomous machines.
- The developer kit includes a Jetson AGX Orin 64GB module, and can emulate all the Jetson Orin modules. It supports multiple concurrent AI application pipelines with the NVIDIA Ampere GPU architecture, next-generation deep learning and vision accelerators, high-speed IO and fast memory bandwidth. Now you can develop solutions using your largest and most complex AI models to solve problems such as natural language understanding, 3D perception, and multi-sensor fusion.
- Jetson runs the NVIDIA AI software stack, and use-case specific application frameworks are available, including Isaac for robotics, DeepStream for vision AI, and Riva for conversational AI. You can save significant time with NVIDIA Omniverse Replicator for synthetic data generation (SDG), and by using NVIDIA TAO toolkit to fine-tune pretrained AI models from the NGC catalog.
- Jetson ecosystem partners offer additional AI and system software, developer tools, and custom software development. They can also help with cameras and other sensors, as well as carrier boards and design services for your product.
- With the computing capability of more than 8 Jetson AGX Xavier systems in a developer kit that integrates the latest NVIDIA GPU technology with the world’s most advanced deep learning software stack, you’ll have the flexibility to create tomorrow’s AI solution as well as today’s.
How buyers should assess the opportunity
For technology buyers and investors, the central question is not whether inference at the edge is useful in principle. It is whether OpenInfer can make heterogeneous deployment operationally simpler and economically better than an existing serving stack or a managed API for a defined workload.
- Benchmark the real workload: Compare time to first token, inter-token latency, p95 and p99 latency, throughput under concurrency, failure or rejection rates, and power use—not just peak tokens per second. Test against relevant alternatives such as vLLM, SGLang, TGI, llama.cpp, Ollama, vendor runtimes, or cloud APIs.
- Verify the hardware and model matrix: Ask which CPUs, GPUs, NPUs, operating systems, model families, quantization formats, context lengths, and multimodal workloads are supported. Establish whether support is native, compatibility-layer based, or limited to specific tested configurations.
- Evaluate operational controls: Check monitoring, recovery, model rollout and rollback, fleet upgrades, multi-tenant isolation, security controls, data residency, air-gapped operation, and service-level agreements.
- Calculate total cost: Include hardware purchases, engineering time, networking, storage, power, observability, orchestration, and maintenance. Local inference may make sense for steady utilization while being less attractive for bursty demand.
- Clarify commercial access: As of August 18, 2026, public company material showed early-access and contact routes but no public pricing. It did not establish a standard per-token, per-node, per-GPU, or enterprise-license rate, or whether all deployments were immediately available. Buyers should ask what is included in a contract, which hardware is supported, and whether updates and support are included.
OpenInfer’s broad approach also has to contend with alternatives that solve different parts of the problem. vLLM is an open-source serving engine relevant to teams operating GPU servers; Ollama offers a simpler local-model entry point; llama.cpp is a lightweight implementation relevant to local and CPU-oriented execution; and TensorRT-LLM is optimized for NVIDIA hardware. Managed services such as the OpenAI API, Amazon Bedrock, Google Vertex AI, and Microsoft Azure AI Foundry can simplify operations and scale with demand, while offering less control over local execution. The right comparison depends on workload, hardware, data requirements, and staffing—not on a blanket claim that one stack is faster or cheaper.
What the funding establishes—and what remains open
The financing and its lead investors are reported facts, while the technical thesis is a mix of company and investor claims. The cited public materials do not establish a valuation or round terms, a detailed supported-hardware matrix, independent performance results, named production customers, or customer-level total-cost savings. Those gaps matter because benchmark mismatch, memory pressure, cold starts, thermal throttling, network overhead in distributed systems, and the difficulty of updating disconnected devices can all erode an apparent advantage.
For personal-finance-minded readers tracking the AI market, the round is best understood as an early financing signal about a potentially important infrastructure category. OpenInfer’s 2026 move toward an Inference OS broadens the ambition beyond the 2025 edge-inference pitch, but the commercial case still depends on reproducible workload-level performance, dependable operations, clear product access, and a favorable total cost compared with existing tools and cloud services.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




