
Deploy predictive maintenance as a controlled reliability-and-cash-flow project, not as a sensor purchase. Start with a small group of high-criticality assets, define the failure modes and maintenance decisions you need to improve, establish a normal operating baseline, and measure results against the plant’s pre-deployment performance. Use vibration as the starting signal for most rotating equipment, add other sensors only when they explain a specific failure mechanism, process data locally when latency or connectivity matters, and connect every actionable alert to the maintenance system.
The financially defensible sequence is: scope a pilot, instrument it correctly, build trustworthy data, validate alerts in live operations, quantify avoided or better-timed work, then scale by asset class. A Microsoft 2026 predictive-maintenance scenario cites a potential 50–70% baseline ROI, but that is a platform-planning scenario rather than a universal industry benchmark. Your business case must come from measured intervention, downtime, labor, spares and availability changes at your own facility.

As an Amazon Associate I earn from qualifying purchases.
What an industrial AI sensor deployment actually includes
Predictive maintenance combines condition sensors, data processing, machine-learning models and a maintenance response. The objective is not to produce an anomaly score; it is to identify a credible deterioration pattern early enough for a maintainer to inspect, repair or schedule an asset before an undesirable failure.
The International Telecommunication Union’s ITU-T Y.4618 reference model divides an AIoT deployment into devices, edge nodes and cloud systems. A practical implementation uses all three layers, with different responsibilities:
#1 Best Overall

- INDUSTRIAL VIBRATION METER – VM-424 WITH REMOTE SENSOR PROBE - Designed for vibration measurement on motors, pumps, compressors, gearboxes, fans and rotating machinery where direct placement of a handheld meter is difficult. The external sensor allows technicians to reach narrow measurement points while keeping the main unit at a safe and comfortable viewing position.
- 3-IN-1 VIBRATION MEASUREMENT – ACCELERATION VELOCITY DISPLACEMENT - Measures Acceleration 0.1–199.9 m/s² (peak), Velocity 0.1–199.9 mm/s (RMS) and Displacement 0.001–1.999 mm (p-p), enabling technicians to evaluate key vibration parameters used in machine condition monitoring and preventive maintenance inspections.
- DUAL FREQUENCY ACCELERATION MODES – 10HZ–1KHZ AND 1KHZ–3KHZ - Low frequency mode supports general machine vibration evaluation such as imbalance or structural vibration, while high frequency mode helps observe higher-frequency vibration components during mechanical diagnostics.
- REMOTE PIEZOELECTRIC SENSOR – STABLE CONTACT MEASUREMENT - External shear-type accelerometer connected by cable allows precise probe positioning on bearing housings, pump casings and motor frames while the display remains easy to read during measurement.
- INTERCHANGEABLE PROBE TIPS – MAGNETIC, SHORT AND LONG CONTACT - Includes magnetic base tip for hands-free contact on metal surfaces as well as short and long probe tips for measurements on flat surfaces, narrow housings and recessed machine components.
| Layer | Typical responsibilities | Why it matters financially |
|---|---|---|
| Sensor device | Measure vibration, temperature, pressure, speed, oil condition, current, acoustics or thermal conditions; perform lightweight preprocessing or machine learning. | Determines installation labor, calibration burden, battery or power needs and the quality of every downstream decision. |
| Edge node | Aggregate signals, add operating context, run time-sensitive inference, deploy models, manage devices and provide local observability. | Can reduce bandwidth charges and keep detection available during intermittent connectivity. |
| Cloud service | Store fleet data, train models across sites, orchestrate deployments, compare asset classes and manage model versions. | Spreads development cost across a fleet and supports centralized governance, but adds connectivity and service costs. |
Deployment is complete only when a validated alert reaches a defined maintenance decision and the outcome is recorded for later model and financial analysis.
1. Scope a bounded pilot before buying hardware
Choose assets where prediction can change a decision
Select a small set of motors, pumps, compressors, gearboxes or similar rotating assets whose failures are costly, detectable and actionable. A suitable pilot has enough failure or degradation history to learn from, or enough maintenance expertise to define meaningful inspection outcomes. A sensor on an inexpensive, noncritical asset may generate interesting data but little economic value.
NIST recommends linking prognostics and health-management use cases to safety, environmental, cost-benefit and operational goals. Siemens describes a progression from scoping and design through deployment, operation and refinement. Use those stages to write a one-page pilot charter before selecting a supplier.
Write the failure and intervention definition
For each asset, record the failure modes you intend to detect: for example, bearing deterioration, imbalance, misalignment, cavitation, lubrication problems or seal degradation. Then specify the lead time maintainers need, the inspection that confirms an alert, the person who owns the decision and the action that follows. “Investigate abnormal vibration within 24 hours” is operational; “use AI to predict failure” is not.
Set success metrics and a baseline
Capture a pre-deployment period long enough to represent normal production, planned stops and routine maintenance. Establish baseline values for unplanned downtime, emergency work, planned-versus-unplanned maintenance, spare-parts usage, overtime, inspection hours, asset availability and production impact. Define acceptable false-alert and missed-failure rates before the first alert is evaluated.
Rank #2
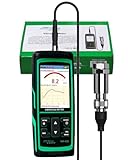
- PROFESSIONAL VIBRATION ANALYZER – VM-428 WITH EXTERNAL SENSOR - Designed for advanced vibration diagnostics on motors, turbines, pumps, compressors and rotating machinery where higher measurement ranges and additional diagnostic parameters are required.
- 5-PARAMETER MACHINE DIAGNOSTICS – A V D FREQUENCY TEMPERATURE - Measures Acceleration 0.1–300 m/s² (peak), Velocity 1–850 mm/s (RMS), Displacement 1–3300 µm (p-p), Frequency 30Hz–14kHz and Temperature, providing multiple diagnostic indicators for machine condition evaluation.
- DUAL FREQUENCY MEASUREMENT CIRCUIT – STRUCTURAL AND HIGH-FREQUENCY MODES - Low frequency mode supports general vibration analysis of machine structures, while high frequency mode allows observation of higher-frequency vibration signals often associated with mechanical wear or bearing conditions.
- REMOTE MAGNETIC SENSOR – STABLE AND REPEATABLE MEASUREMENTS - External piezoelectric shear-type probe with magnetic base allows secure placement on metal housings, supporting stable readings during inspection of motors, gearboxes and rotating equipment.
- ISO MACHINE CONDITION RATING INDICATION - Built-in vibration severity scale based on ISO vibration classification helps technicians visually interpret measured velocity levels during machine condition evaluation.
| Pilot element | Decision to document |
|---|---|
| Asset boundary | Which asset IDs, locations and operating regimes are included. |
| Failure scope | Which failure mechanisms are in scope and which are explicitly excluded. |
| Lead time | How many hours or days are needed to inspect, obtain parts and schedule work. |
| Alert policy | Severity levels, confirmation checks and who can authorize a work order. |
| Financial baseline | Pre-pilot downtime, labor, spares, contractor, inspection and production-loss measures. |
| Exit gate | The operational and financial evidence required before adding more assets. |
2. Match each sensor to failure physics
Use vibration first for rotating machinery
Vibration is usually the first modality to evaluate on rotating equipment because mechanical defects alter the machine’s time- and frequency-domain behavior. Texas Instruments describes an industrial piezoelectric (IEPE) vibration architecture in which a sensor is mounted to equipment, analog signal conditioning prepares the signal, an analog-to-digital converter captures it, and time- and frequency-domain analysis compares the result with failure models. Fast Fourier Transform (FFT) analysis is one method for separating frequency components associated with different conditions.
Mounting location, orientation, bandwidth and sampling rate determine whether the signal contains useful fault information. A poorly mounted sensor can create a data-quality problem that no model can repair. Record the mounting method and location in the asset’s metadata so a later technician can reproduce the measurement.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Add a second modality only for a defined diagnostic reason
Intel’s hydraulic-pump example combines vibration, oil pressure and fluid speed. That pattern illustrates the rule: add a signal when it explains a known failure mechanism or materially improves diagnosis. Temperature can support overheating or lubrication analysis; pressure can reveal hydraulic or pneumatic problems; speed provides operating context; oil measurements can indicate contamination or wear; acoustic microphones can expose leaks or high-frequency mechanical changes; thermal measurements can identify abnormal heat distribution; and electrical current can provide a nonintrusive indicator of load or motor behavior.
| Signal | Use when it explains | Implementation questions |
|---|---|---|
| Vibration | Mechanical defects in bearings, couplings, gears, shafts or rotating assemblies. | Mounting method, frequency bandwidth, sampling rate, sensor orientation and temperature range. |
| Temperature or thermal | Overheating, lubrication problems, electrical hot spots or abnormal heat patterns. | Sensor placement, emissivity or contact conditions, ambient variation and response time. |
| Pressure | Hydraulic, pneumatic, cavitation or flow-related deterioration. | Pressure range, process connection, pulsation, fluid compatibility and calibration interval. |
| Speed | Operating context needed to interpret vibration, load or process signals. | Rotation range, synchronization accuracy and availability of a reliable reference. |
| Oil condition | Contamination, viscosity change, particles or wear products. | Sampling method, laboratory correlation, fluid type and maintenance handling. |
| Acoustic | Leaks, friction, impacts or high-frequency changes not visible in slower signals. | Microphone placement, background noise, enclosure effects and bandwidth. |
| Electrical current | Motor load, imbalance or electrical behavior that correlates with mechanical condition. | Electrical safety, phase configuration, load variation and isolation requirements. |
Check installation and environmental constraints
Before ordering, verify the mounting surface, cable route or wireless range, available power, temperature and ingress environment, hazardous-area requirements, calibration process, sampling schedule and maintainability. STMicroelectronics describes industrial accelerometers, inertial measurement units and acoustic microphones used in smart sensor nodes and gateways for condition monitoring. The correct device is the one that survives the plant and produces a repeatable signal, not merely the one with the highest advertised specification.
3. Build a trustworthy data foundation
Capture operating context, not just sensor values
Store every measurement with asset identity, timestamp, operating state, load, speed, environmental conditions, sensor location, calibration status and maintenance history. Include starts, stops, process changes, inspections, part replacements, lubrication, alignment and other interventions. Without context, an algorithm may classify a normal change in production rate as a fault.
Rank #3

- 【5-in-1 Diagnosis】The vibration meter supports measurements of Acceleration 0.1–300 m/s² (peak), Velocity 1–850 mm/s (RMS), Displacement 1–3300 µm, Frequency 30 Hz–14 kHz, Temperature 14~140°F. The vibrometer gauge meets the common predictive maintenance and condition check needs in workshops and production sites.
- 【Wide Range of Applications】This digital vibration analyzer is suitable for motors, HVAC systems, pumps, fans, generators, compressors, turbines, bearings, etc. The tester features ISO vibration intensity classification. You can quickly get a preliminary assessment of machine/vehicle vibration. Appropriate for mechanical maintenance technicians, engineers, QC inspectors, or even beginners.
- 【Large Storage & Transmission】This vibration meter supports automatic/manual recording (stores up to 8 MB ≈397,000 data points). It can transfer CSV and BMP files via PC software (compatible with Windows systems) or be used as a small-capacity USB drive. Handy for long-term trend analysis and batch data archiving of equipment records.
- 【Clear Display & Stable Measurement】The easy-to-read backlit screen enables data collection and interpretation under various lighting conditions. It clearly shows line graphs and real-time statistics of maximum/minimum/average values. The separate probe comes with a strong magnetic sensor, which helps access hard-to-reach areas and minimizes the impact of your movements on the results.
- 【User-friendly Design】The vibration detector comes with a portable carrying case for outdoor use. It supports automatic high/low-speed circuit switching, adjustable sampling time, screen brightness, calibration, unit switching, automatic power-off, machine-grade selection, low battery indicator. The included manual provides a detailed explanation of each function. Setup takes only a few seconds.
Establish normal behavior before training
Baseline creation should cover the operating regimes in which the asset is expected to run. Separate data collected during commissioning, abnormal operation and known maintenance from ordinary production. A vendor demonstration dataset can illustrate an algorithm, but it should not be treated as representative of your plant’s machines, loads or environment.
Make labels operationally useful
Labels should identify the confirmed failure or inspection result, the time it became observable, the maintenance action and the condition after repair. “Work order closed” is not automatically a failure label. Have reliability engineers review whether the evidence supports the label and retain uncertainty when a cause was never confirmed.
4. Choose the device-edge-cloud split
Run local processing when delay or resilience matters
Preprocess or infer at the edge when a response must be fast, connectivity is intermittent, sensor bandwidth is high, data privacy limits transmission, or the plant must continue detecting conditions during a network outage. Local processing can reduce raw waveform transmission by sending features or events while retaining selected raw windows for diagnosis.
Use cloud services for fleet learning and governance
Cloud systems are suited to centralized training, large-scale storage, cross-site comparisons, dashboards, orchestration and controlled model distribution. Microsoft’s predictive-maintenance scenario explicitly combines edge data processing with cloud analytics. Keep the division explicit: the edge should continue its approved inference function if the cloud is unreachable, and cloud updates should not silently replace a model running on production equipment.
Design the handoffs
| Question | Device or edge answer | Cloud answer |
|---|---|---|
| Where is raw data reduced? | At the sensor or gateway when bandwidth or latency requires it. | Retain selected raw segments for model development and audit. |
| Where is an urgent alert generated? | Locally when seconds or minutes matter. | Centralize the event for fleet visibility and escalation. |
| Where are models trained? | Use local adaptation only under controlled governance. | Train and compare versions using fleet-wide data and validation sets. |
| Where are versions controlled? | Enforce the approved package and rollback image. | Maintain the registry, approvals, release history and deployment status. |
5. Turn an alert into maintenance work
An anomaly score is not a work order. Define the workflow before enabling notifications.
Recommended Free Tools
Rank #4

- 【Integrated Vibration Sensor】Real-time capture of 3-axis vibration and temperature data: Vibration displacement (0~30000um) + Speed (0~50mm/s) + Amplitude (0~180°) + Operating temperature (-20°C~60°C). Vibration and shock omnidirectional measurements can prevent breakdowns and repair costs.
- 【BLE 5.0 Low Power】 50m transmission distance, approximately 8 hours battery life. Bluetooth 5.0 is compatible with Android/iOS systems. The WITMOTION APP supports connecting sensors on smartphones (up to 4 on the same phone). It can also be connected to a computer via TYPE-C, making it easy for users to choose the best connection.
- 【Easy Install & Use】The wireless design allows the sensors to be installed on machine parts that are difficult to access. A small and portable sensor designed with strap holes at both ends that can be used and go anywhere.
- 【Analysis Vibration Sensor System】Condition monitoring and vibration analysis are seamlessly integrated with WITMOTION PC software, making it quick and easy to analyze and visualize data. Maintenance teams can set it up as needed.
- 【Attitude Measurement More Accurate & Reliable】Sensors integrated R&D fusion algorithm, low noise level, and increasing measurement accuracy ensuring stable data output. WITMOTION has been focusing on the sensor field for 10 years, providing professional attitude measurement solutions globally.
- Classify severity. Set thresholds for advisory, inspection-required and urgent conditions, with the operating context that qualifies each threshold.
- Require confirmation. Specify the trend, secondary measurement, visual check or technician test that should confirm the condition.
- Recommend an action. Include the inspection step, safe operating instruction, expected parts and the time window for intervention.
- Route the event. Connect the condition-monitoring system to the CMMS, EAM, SCADA or historian system used by the responsible team. Preserve the asset ID and alert version during transfer.
- Record the outcome. Capture whether the alert was confirmed, dismissed, deferred, linked to a failure or followed by a planned repair.
- Feed closure data back. Use the maintenance result to improve labels, thresholds and model evaluation rather than allowing closed work orders to disappear into a separate system.
Include production, reliability, maintenance, information technology and safety stakeholders in the approval path. A technically accurate alert that nobody can act on has no realized maintenance value.
6. Validate models in live operating conditions
Separate development, validation and live monitoring
Keep model-development data separate from validation data and from the live monitoring stream. Test across loads, speeds, seasons, product grades and known operating transitions. Do not allow repeated tuning against the same live events to create an overly optimistic result.
Track the measures that affect decisions
- False positives: alerts that required review but were not supported by an actionable condition.
- Missed failures: failures that occurred without a useful preceding alert.
- Detection lead time: the interval between a reliable alert and the point at which intervention was required.
- Alert-to-action time: how quickly a responsible team inspected or scheduled work.
- Maintenance avoidance or acceleration: emergency work prevented, or planned work moved to a safer and less disruptive window.
- Asset availability and unplanned downtime compared with the pre-deployment baseline.
Keep a human decision gate
Technicians and reliability engineers should be able to inspect the evidence behind an alert, override a recommendation and document why. IEEE P4501’s manufacturing physical-AI scope emphasizes lifecycle terminology, functional requirements under interference such as vibration and dust, secure data governance and human-system interaction. Those requirements are practical safeguards against automating an ambiguous maintenance decision.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.7. Secure the complete lifecycle
Security is an operating requirement because a compromised sensor, gateway or model can create unsafe maintenance instructions or hide a real fault. ITU-T Y.4618 calls for secure communication, mutual authentication and encryption, secure model and data lifecycle management, remote monitoring and diagnostics, automated status monitoring and secure over-the-air updates.
- Authenticate devices and services mutually rather than trusting a plant network by location alone.
- Encrypt data in transit and protect stored maintenance and production records.
- Sign, approve and inventory firmware, edge software and model packages.
- Maintain rollback versions for firmware and models, with a tested recovery path.
- Log who approved, deployed, changed or disabled a threshold and when.
- Monitor missing data, unusual reporting rates, clock drift, sensor health and gateway status.
- Restrict remote diagnostics and updates to authorized personnel and documented maintenance windows.
- Define retention and access rules for production, employee and supplier data.
8. Build a defensible predictive-maintenance ROI case
Use a before-and-after decision model
Measure financial impact against the baseline rather than valuing every alert. A simple planning equation is:
Best Value
Net benefit = avoided failure loss + reduced emergency labor and parts premium + recovered production contribution + reduced routine inspection cost − sensor, connectivity, software, integration, training and maintenance cost.
ROI = (net benefit ÷ project cost) × 100.
Use the same asset population and comparable operating period on both sides of the calculation. State whether production impact is measured as lost sales, contribution margin or another internal value; do not silently treat revenue as profit.
Separate one-time and recurring costs
| Cost category | Examples to budget |
|---|---|
| One-time deployment | Sensor installation, mounting changes, gateway or edge hardware, integration, baseline engineering, model development and workforce training. |
| Recurring operation | Connectivity, cloud storage and compute, calibration, sensor replacement, software support, security monitoring and model review. |
| Change-management cost | Technician time for confirmation, new inspection routes, approval meetings and updates to maintenance procedures. |
| Risk reserve | Spare devices, rollback capacity, troubleshooting and remediation of poor data quality. |
Interpret published ROI carefully
Microsoft’s 2026 scenario page gives a 50–70% baseline ROI figure for planning a predictive-maintenance platform. It is not an audited, cross-industry success rate or a guarantee for a particular plant. The canonical material reviewed for this topic provides no authoritative cross-industry payback or success statistic. Treat the scenario as a sensitivity range to test, then replace it with measured results from the pilot.
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Repair Windows errors before they cause bigger problems3Fix the driver behind crashes, sound loss and screen glitchesUse staged investment gates
- Approve instrumentation only after the failure and intervention scope is clear.
- Release integration and model-development budget after data completeness and baseline quality pass review.
- Authorize expansion only when alert quality, maintenance response and financial measures improve against the baseline.
- Reassess the business case when operating regimes, equipment, thresholds or maintenance practices change.
9. Scale from pilot to asset class
Scale only after the pilot performs across the operating regimes that matter and the workflow produces measurable operational impact. Expand first to assets with comparable design, duty cycle and failure physics; do not assume a model trained on one pump transfers safely to every pump.
At each expansion, verify sensor installation consistency, data completeness, calibration status, model version, threshold ownership and CMMS closure quality. Continue monitoring sensor drift and missing data. Retain a rollback path for every model and firmware update, and keep a human review process for newly deployed asset classes.
Common deployment failures and practical fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| Many alerts during normal production changes | Operating load, speed or process state was not included as context. | Segment the baseline by operating regime and add the relevant context signal. |
| Unstable vibration readings | Inconsistent mounting, unsuitable location, environmental interference or calibration drift. | Standardize mounting, document locations, inspect the installation and verify calibration. |
| Alerts arrive after the failure | Sampling, transmission or inference latency is too high, or the chosen signal changes too late. | Move time-sensitive processing to the edge, review sampling and add a modality tied to the earlier failure mechanism. |
| Technicians ignore notifications | Severity is unclear, confirmation steps are missing or alerts are not connected to the work system. | Define escalation, inspection instructions and CMMS/EAM routing; review false-alert burden. |
| Model looks strong in testing but weak in operation | Development data did not represent plant loads, seasons or maintenance conditions. | Separate validation data, test across regimes and rebuild the baseline from plant history. |
| Cloud outage stops detection | All inference was centralized despite a need for local resilience. | Run approved preprocessing or inference at the edge and queue data for later synchronization. |
| Unauthorized or untraceable changes | Firmware, model and threshold governance is informal. | Require authentication, signed or controlled updates, approvals, version inventory and audit logs. |
Deployment checklist
- Critical assets, failure modes, lead time and intervention decisions are written down.
- A pre-deployment baseline covers downtime, maintenance, labor, spares and availability.
- Sensor physics, mounting, bandwidth, sampling, environment and calibration are appropriate.
- Asset identity, operating context, sensor metadata and maintenance events are captured together.
- Device, edge and cloud responsibilities are explicit, including outage behavior.
- Alerts have severity, confirmation, escalation, work-order routing and closure feedback.
- Development, validation and live data are separated, with false positives and missed failures tracked.
- Authentication, encryption, update control, rollback, monitoring and auditability are implemented.
- Pilot results are compared with the baseline before expansion, and the financial model is updated with measured values.
Bottom line
The safest deployment path is a small, measurable pilot on high-consequence rotating assets. Let the failure mechanism determine the sensor, let latency and resilience determine where inference runs, and let the maintenance workflow determine whether an alert is useful. Treat data quality, validation, security and financial measurement as engineering deliverables. Once the pilot demonstrates better-timed work and a positive change against the pre-deployment baseline, scale by comparable asset class with version control and human oversight.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.
The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →



