What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Some links on this page are affiliate links: if you buy through them we may earn a commission, at no extra cost to you.
Data tiering can reduce the energy used to store and move AI data, but it does not directly reduce the electricity GPUs consume during training or inference. It works by keeping frequently used data on fast storage, shifting rarely accessed data to slower, higher-capacity tiers, and deleting data that no longer needs to exist. The net benefit depends on what the workload actually reads, how often data must be retrieved, where compute runs, and whether slower access causes GPUs to wait.
For AI teams, the practical goal is not to put as much data as possible into the coldest tier. It is to retain each dataset, checkpoint, index, and log on the least resource-intensive tier that still meets performance, recovery, compliance, and reproducibility needs—and to measure the whole workflow rather than storage price alone.
What data tiering means for an AI system
Data tiering is the practice of placing information on different storage types or service classes according to how often it is accessed and what its performance, retention, and recovery needs are. A training dataset read repeatedly during every epoch has different requirements from a checkpoint kept for historical provenance or a temporary file left behind by a failed data-processing run.
“Hot,” “warm,” “cold,” and “archive” are useful operational labels, not universal standards. Providers use different names and performance characteristics. A typical arrangement looks like this:
#1 Best Overall
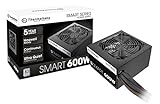
- Delivers 600W Continuous output at plus 40℃. Compliance with Intel ATX 12V 2. 31 and EPS 12V 2. 92 standards
- 80 PLUS Certified – 80% efficiency under typical load. Power good signal is 100-500 millisecond
- Supports (2) PCI-E 6 plus 2pin Connectors. Active (PFC) Power Factor Correction, MTBF: 100, 000 hours
- Industry Grade Protections: (OPP) Over Power Protection, (OVP) Over Voltage Protection, (SCP) Short Circuit Protection
- Hold up time is 16 millisecond minimum within 60 percent load. Input frequency range 50 - 60 in Hz
| Tier | Typical storage | AI data that may fit | Access expectation |
|---|---|---|---|
| Hot | Local NVMe, SSD arrays, high-performance file systems, or premium object storage | Active training shards, serving indexes, feature stores, current checkpoints, inference caches | Low latency; frequent reads and high throughput |
| Warm | HDD clusters or standard object storage | Recently completed datasets, reusable checkpoints, evaluation sets, current model versions | Periodic access; moderate latency may be acceptable |
| Cold | Nearline or infrequent-access object storage, archive HDD | Older datasets, infrequently used logs, older checkpoints, disaster-recovery copies | Infrequent access; retrieval may take longer or cost extra |
| Deep archive | Tape or deep-archive cloud storage | Long-term regulatory records, research provenance, rarely recalled raw data | Rare access; restoration may take hours or longer |
| Delete | Lifecycle expiration or approved data-governance removal | Obsolete duplicates, expired temporary outputs, failed-run artifacts with no recovery value | Not retained |
Choose a tier using access frequency, latency and throughput requirements, retention period, recovery-time objective, durability and availability needs, compliance and data-residency constraints, and retrieval and transfer costs. The energy characteristics of a tier also depend on the hardware, its utilization, cooling, replication, region, and how often data is recalled.
Where the potential energy savings come from
Lower-power storage for less demanding data. High-performance drives are valuable when a workload needs their speed, but not every retained byte needs to sit on the fastest media. ENERGY STAR recommends reserving high-speed drives for applications that need instantaneous response and using slower storage where performance requirements allow. Its guidance also describes automated tiering as a way to move data among storage types according to capacity and performance needs. ENERGY STAR: efficient data-storage measures.
Less high-performance capacity to power and cool. Moving inactive data off hot storage may let an organization provision fewer high-performance devices. That can reduce the associated rack power and cooling demand, and potentially reduce hardware replacement and embodied impacts. The result depends on whether the move actually changes the amount of equipment deployed; a bookkeeping change between cloud classes does not, by itself, prove a particular electricity saving.
Recommended Free Tools
Fewer unnecessary copies. AI pipelines can accumulate raw, cleaned, tokenized, and sharded data; caches; training snapshots; evaluation subsets; replicated checkpoints; and cross-region backups. Tiering only one copy while leaving duplicates active elsewhere limits the benefit. A catalog, shared source of truth, deduplication where appropriate, and lifecycle rules can reduce retained volume and the resources needed to maintain it. AWS’s sustainability guidance recommends data-minimization and retention practices, including removing data that is no longer needed. AWS Well-Architected sustainability patterns.
Rank #2

- Delivers 500 Watt Continuous output at plus 40 degree. Compliance with Intel ATX 12 Volt 2.31 and EPS 12V 2.92 standards
- 80 PLUS Certified, 80 percentage efficiency under typical load
- Supports (2) PCI E 6plus2pin Connectors. Active (PFC) Power Factor Correction, MTBF: 100,000 hours
- Industry Grade Protections: (OPP) Over Power Protection, (OVP) Over Voltage Protection, (SCP) Short Circuit Protection
- High Quality Components
Less data movement. Transfers, archive recalls, and restaging have their own energy, time, and sometimes financial costs. Google recommends placing compute-intensive workloads such as AI training in the same region as their data source where practical, to reduce transfer-related energy. Google Cloud sustainability guidance for storage.
Deletion rather than indefinite storage. If an intermediate output has expired, duplicates a canonical source, or can be cheaply recreated and has no retention value, deleting it avoids keeping, replicating, transferring, and backing up those bytes. But “reproducible” is not automatically a reason to delete: regeneration may require a large compute job, and legal, scientific, or business needs may require preservation.
Storage and transmission belong in the environmental boundary of an AI system, alongside training, inference, cooling, hardware, and other infrastructure. The ITU’s 2026 guidance calls for environmental assessment with an explicit system boundary and energy and life-cycle information; it does not establish one fixed storage share for every AI system. ITU-T L.1801 (2026): guidelines for assessing AI environmental impact.
Classify AI data by its actual role
Training datasets
Keep data hot or readily accessible when jobs repeatedly read it, workers need high aggregate throughput, or random shuffling and concurrent reads are likely to starve GPUs on a slower path. Large does not mean cold: a large dataset used every epoch may be a poor archive candidate. For completed datasets retained for reproducibility but rarely reused, warm, cold, or archive storage may be suitable, subject to restore time and retention needs. Google specifically identifies older AI training datasets and infrequently accessed backups as candidates for lower-access classes, with Archive intended for long-term retention.
Rank #3

- 80 PLUS GOLD CERTIFIED
- 10-year limited warranty, guaranteeing long term reliable operation
- Fully modular design
- ATX 3.1 & PCIE 5.1
Checkpoints and model artifacts
Keep the latest checkpoint and the version needed for immediate rollback on hot or warm storage. Move older checkpoints only after deciding which milestones have scientific, operational, or compliance value. Delete failed, superseded, or reproducible artifacts when they have no retention purpose. Frequent saves, replication, and many small files can erode expected savings, so look at the whole checkpoint workflow rather than the storage-class rate alone.
Logs and telemetry
Recent operational logs may need quick access. Security and audit logs should follow retention policy. Debug logs can often expire quickly; historical high-volume telemetry may be aggregated, sampled, or downsampled if full resolution is no longer useful. Google recommends reviewing large data volumes and using aggregation or sampling where full-resolution records are not required.
Embeddings and vector indexes
Keep actively queried indexes on storage that meets serving latency and availability requirements. Older embedding versions, inactive tenants, and rebuildable historical indexes may be archived if they are not on a live request path. Do not archive the only copy merely because it is idle: rebuilding embeddings or an index can consume substantial CPU or GPU energy and delay service.
Do these 3 things before closing this tab:
1Clear out junk files and repair common Windows errors2Fix the driver behind crashes, sound loss and screen glitches3Repair Windows errors before they cause bigger problemsTemporary data, caches, and derived outputs
Set explicit expiration rules for shuffle files, temporary transformations, failed-run outputs, duplicate shards, and stale caches. Preserve lineage, checksums, licenses, and transformation recipes when needed for reproducibility even if the bulky source or intermediate files move to archive or are removed.
Rank #4
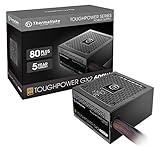
- [CERTIFIED GOLD] - Supporting 80 Plus Gold efficiency up to 90% and optimized for C6/C7 States ready
- [NON MODULAR CONNECTORS] – Main Power (24 pin) x 1/ ATX 12V (4plus4 pin) x 1/ SATA (5 pin) x 6/ PCI-E (6plus2 pin) x 2/ peripheral (4 pin) x 3/ FDD x 1
- [ULTRA QUIET 120MM FAN] – Dynamic Bearing fan s superior cooing performance and silent operation
- [HIGH QUALITY CAPACITORS] - High quality capacitors provide superb performance and reliability
- [LOW RIPPLE NOISE] – Ensure excellent power supply stability Keep performance-critical components such as VGA card to operate reliably for longer
A practical tiering policy: nine steps
- Inventory the data estate. Catalog raw and processed datasets, feature tables, checkpoints, model artifacts, embeddings, indexes, logs, caches, temporary outputs, backups, and replicas. Record an owner and purpose for each class.
- Measure access before setting age thresholds. Collect last-read time, read frequency, bytes read per job, sequential versus random access, object size, and access by workload. A two-year-old benchmark used daily may belong on hot storage; yesterday’s failed-run output may have no reason to remain.
- Assign operational classes. Define what “hot,” “warm,” “cold,” “archive,” and “disposable” mean for your own service—for example, in terms of acceptable latency, frequency of use, and recovery time. Avoid treating generic 30-, 60-, or 90-day rules as universally correct.
- Define retention and deletion rules. Set timelines for failed jobs, temporary transformations, debug logs, redundant copies, superseded versions, and regenerable indexes. Add exceptions for legal holds, security investigations, and research or audit requirements. AWS recommends lifecycle policies to enforce deletion timelines and keep retained data aligned with business needs. AWS: optimizing deep-learning workloads for sustainability.
- Compare retaining, regenerating, and deleting. Estimate retrieval and restore effort as well as the compute and energy needed to recreate data. A file that is cheap to regenerate may still be expensive to reproduce if it requires GPU-intensive preprocessing.
- Choose media or a storage class. Use SSD/NVMe for active random I/O and tight latency requirements; capacity-oriented HDD or standard object storage for less demanding reusable data; infrequent-access tiers for retained data read rarely; archive or tape for long-lived data that can tolerate slow restoration. These are starting points, not fixed rules.
- Automate transitions carefully. Apply lifecycle rules or storage-management policies based on observed access, age, ownership, and retention requirements. Use a quarantine or waiting period before irreversible deletion or deep archival, and create exceptions for data tied to active jobs or legal holds.
- Stage data before planned training. Identify the required input, restore or copy it to a warm or hot staging area, verify checksums and permissions, warm local caches if needed, and only then start the GPU job. Remove the staging copy after its defined window. This reduces the risk of paying for GPUs to wait on an archive recall.
- Test recovery and review the policy. Run restore drills, measure latency and failure modes, check compliance and data residency, and revisit classifications when workloads change. A tier is not a safe retention plan until its restore path has been tested.
A useful decision is a combination rather than a single “days since last access” value:
tier decision = access frequency + latency and throughput needs
              + retention value + rebuild cost + compliance requirements
+ retrieval and transfer cost + data localityCloud storage examples and caveats
AWS S3
S3 Intelligent-Tiering is designed for changing or unpredictable access patterns and automatically moves eligible objects among access tiers. It has a per-object monitoring and automation charge; objects smaller than 128 KB are not monitored for automatic tiering and are charged at Frequent Access rates. Archive tiers are opt-in. AWS describes its Archive Access tier as taking hours to retrieve and Deep Archive Access as potentially taking longer. Review current S3 pricing and class behavior for the specific region and workload.
S3 Glacier Flexible Retrieval and S3 Glacier Deep Archive objects must be restored before direct access; restoration creates a temporary accessible copy rather than making archive data instantly available. AWS documents minimum storage durations of 90 days for Glacier Flexible Retrieval and 180 days for Deep Archive, with prorated early-deletion charges. Archived objects also incur 40 KB of metadata overhead per object (8 KB billed at S3 Standard rates and 32 KB at the archival rate). These details matter for short-lived archives and repositories containing many tiny objects. AWS S3 archival storage details.
Google Cloud Storage
Google Cloud Storage offers Standard, Nearline, Coldline, and Archive classes. Its listed minimum storage durations are none, 30 days, 90 days, and 365 days, respectively. Early deletion charges can apply if an object is deleted, replaced, or moved before its minimum duration. Check the current Google Cloud Storage pricing for the region, operations, retrieval, and network charges that apply to your use case.
Best Value

- 80 PLUS GOLD CERTIFIED
- 10-year limited warranty, guaranteeing long term reliable operation
- Fully modular design
- ATX 3.1 & PCIE 5.1
For predictable aging, explicit lifecycle rules can transition data between classes. Google recommends Nearline or Coldline for older training datasets and infrequently accessed backups, and Archive for long-term retention. It also recommends colocating compute-intensive jobs with their data when practical. Google Cloud: optimize storage for sustainability.
Neither a lower price nor the word “archive” establishes a quantified environmental benefit. Cloud billing, operational electricity, embodied hardware impact, cooling, transfer, and retrieval are separate factors. Provider-specific environmental data and the workload’s actual behavior are needed for a firm comparison.
When tiering can backfire
- GPU starvation: If training repeatedly reads data from a slow tier, longer job duration or idle accelerators can outweigh the energy saved on storage. Measure energy per completed run, not just energy per stored terabyte.
- Archive recall on a live path: Delayed restoration is unsuitable for synchronous inference dependencies or incident-response workflows that require immediate access.
- Expensive or frequent restores: Rehydration, checksum verification, decompression, restaging, and network transfer all consume resources. Repeated recalls can make a cold tier the wrong choice.
- Wrong-way locality: A cheaper class in another region can add transfer energy, latency, egress costs, and data-residency complications. Keep data near compute when practical.
- Small-object overhead: Millions of tiny objects can incur per-object metadata, requests, and management overhead. Consolidate shards into larger objects where the data pipeline supports it.
- Short retention in a long-minimum tier: Early deletion or replacement may trigger charges, as with the documented AWS and Google minimum durations. Match the tier’s minimums to expected retention.
- Unneeded replicas remain hot: Snapshots, caches, backups, and cross-region copies can cancel out the effect of moving one canonical copy. Audit replication separately and align it with recovery requirements.
- Regeneration is not free: Rebuilding synthetic data, embeddings, or derived datasets may cost more energy and time than retaining them. Include the rebuild workload in the decision.
- Provenance or compliance is lost: Retention rules must account for research reproducibility, licenses, privacy obligations, legal holds, and data-residency requirements. Preserve necessary metadata and lineage.
How to tell whether the change helped
Set a baseline before changing tiers and define a boundary that includes the work the policy may shift elsewhere. Track storage energy where measurable, but report it separately from whole-job energy. Useful measures include:
PC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware match- kWh per stored TB-month, if provider or facility data is available;
- kWh per training run or per training sample/token;
- GPU idle or underutilized time attributable to data waits;
- dataset throughput, archive recall volume, and restore time;
- network bytes transferred and cross-region movement;
- hot-storage capacity and utilization, plus replica count;
- failed or delayed jobs, retrieval charges, and recovery-test results;
- cooling or facility overhead where it can be measured.
For a useful before-and-after comparison, consider:
whole-workflow impact = storage + cooling overhead + transfers
                      + retrieval and staging + extra compute from slower access
Report the scope, period, workloads, and assumptions. Electricity use, carbon emissions, embodied impacts, and water use are related but distinct measures; a reduction in one does not automatically imply the same proportional reduction in all the others. If direct kWh data is unavailable, say so and use operational indicators such as storage capacity, transfer volume, and GPU wait time without presenting them as measured energy savings.
Quick Recap
Decision checklist
- Is this data read frequently or needed on a latency-sensitive path?
- Can the job or service tolerate the tier’s actual restore delay?
- Would retrieval or regeneration consume more resources than retaining the data?
- Are duplicate copies, snapshots, caches, and replicas included in the policy?
- Is storage close to the compute region?
- Will minimum storage durations and early-deletion rules fit the retention plan?
- Are small-object overhead and retrieval charges understood?
- Has recovery been tested, and are compliance exceptions in place?
- Could slower access increase training time or reduce GPU utilization?
- Can the data be safely deleted instead?
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.



