Free tools Windows power users keep installed
One-click scans. No signup required.
Some links on this page are affiliate links: if you buy through them we may earn a commission, at no extra cost to you.
Google’s AI-focused venture fund and Nvidia invested in CentML, a Toronto-founded startup that aims to help organizations get more useful work from the GPUs they already have. The $27 million seed round, announced on October 25, 2023, did not add physical chips to the market: CentML sells optimization and deployment software intended to improve how machine-learning workloads use existing hardware.
What CentML does—and what it does not do
Founded in 2022, CentML works in the software layer of AI infrastructure. It does not design or manufacture chips. Its stated goal is to identify inefficient machine-learning workloads and help teams run them more effectively on available accelerators. The company was founded in Toronto, and 2023 coverage reported plans to expand its presence in Silicon Valley. CEO and co-founder Gennady Pekhimenko is a machine-learning-systems researcher and University of Toronto computer-science professor; the company said its founders and team had experience at Amazon, Google, Nvidia and IBM. CentML’s announcement and Data Center Knowledge’s report describe the company and its approach.
The distinction matters: better utilization can increase effective capacity, but it cannot create GPUs or guarantee access to them. AI teams still need suitable accelerators, memory, networking, storage and power. If hardware is unavailable, optimization software alone cannot fill the gap.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Clear out junk files and repair common Windows errors3Scan for outdated or missing drivers - takes under a minuteWho invested and how much
CentML announced a $27 million seed round on October 25, 2023, led by Gradient Ventures, Google’s AI-focused venture fund. The company named Radical Ventures, Nvidia, Deloitte Ventures and Thomson Reuters Ventures as participants. Google’s involvement here means an investment by Gradient Ventures; the announcement does not establish that Google’s operating business adopted CentML or guaranteed its technology. Nvidia’s investment likewise does not make CentML an Nvidia product.
#1 Best Overall

- System Compatibility Note: This 2-slot card measures 271 x 112 x 39 mm and requires a single 12V-2x6-pin power connector. Please verify chassis and PSU compatibility before purchase.
- Dedicated Support: Please contact us directly through Amazon for any product questions or assistance you may require.
- Professional Intel Arc Pro B70 GPU: Built on the Intel Xe2-HPG architecture, it features 32 Xe cores and 256 XMX engines, designed to accelerate AI, rendering, and complex visualization workloads.
- Massive 32GB GDDR6 VRAM: Equipped with 32GB of high-speed GDDR6 memory on a 256-bit bus, running at 19 Gbps, which allows for handling large AI models and complex datasets locally.
- High-Performance Engine Clock: Delivers an engine clock of 2540 MHz, providing the compute power needed for demanding professional applications and AI inference.
TechCrunch reported that CentML had raised money in 2022 and that the extended seed financing brought its total capital raised to approximately $30.5 million. That cumulative figure is TechCrunch’s reporting, separate from the $27 million round announced by CentML. The cited materials do not disclose Nvidia’s individual investment amount. CentML’s funding announcement and TechCrunch’s coverage provide the round details.
Why GPU efficiency became an investment thesis
During the generative-AI expansion in 2023, demand for advanced GPUs rose sharply. The constraint was not simply that hardware was expensive: organizations could also face limited cloud allocations or long waits. At the same time, owning or renting a GPU did not guarantee that it stayed busy doing useful computation.
A workload can lose time to data loading, memory movement, synchronization between devices, scheduling, inefficient kernels or an imbalance between parts of a model. Larger models and expanding inference demand add pressure. Improving utilization or reducing the compute needed for a task can therefore let a team serve more requests or run more experiments with a fixed pool of hardware. CentML cited an estimate of roughly 30% average GPU utilization, but the available coverage does not establish a methodology that would make that number a universal, market-wide measure. Data Center Knowledge and TechCrunch discuss the utilization problem and the startup’s response.
Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware matchPC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Rank #2

- NVIDIA Volta GV100 Architecture — 4,608 CUDA Cores, 640 1st-Gen Tensor Cores delivering 14 TFLOPS FP32 and 112 TFLOPS deep learning performance for AI training, inference, HPC, and scientific computing workloads
- 32GB HBM2 ECC Memory — 900 GB/s Bandwidth — High-bandwidth memory on a 4096-bit bus with ECC error correction provides the memory capacity and throughput required for the largest AI models, simulations, and datasets
- PCIe 3.0 x16 Interface — 250W TDP — Standard PCIe Gen3 connectivity with passive cooling designed for enterprise rack server deployment in HPE ProLiant, Dell PowerEdge, and Supermicro platforms with adequate chassis airflow
- NVLink — Scale to 96GB Unified Memory — Connect two V100 GPUs via NVLink at 300 GB/s bi-directional bandwidth to scale GPU memory from 32GB to 96GB for larger AI training and HPC workloads
- Multi-Precision Computing — Supports FP64 (7 TFLOPS), FP32 (14 TFLOPS), FP16 (112 TFLOPS) and INT8 precision modes for flexible deployment across training, inference, and scientific simulation workloads
How the software is intended to work
CentML describes a workflow that profiles a workload, diagnoses bottlenecks, evaluates deployment options and optimizes execution for target hardware. TechCrunch characterized the product as combining bottleneck detection, deployment-cost prediction and compiler-based optimization. At a high level, the process is:
- Profile the workload: Observe model training or inference to find where time and hardware resources are being spent.
- Predict deployment trade-offs: Estimate time, cost and, according to the company, energy use across hardware configurations.
- Optimize for the target: Use a compiler or other hardware-aware methods to generate or select a more suitable execution plan or code.
- Deploy and manage: Orchestrate workloads and monitor how they perform in operation.
The company’s November 2024 platform announcement described a broader deployment offering, including GPU selection and infrastructure planning as well as autoscaling, traffic management and monitoring. That development extends beyond optimizing an individual training run: it addresses choices teams make before deployment and operational adjustments after a model is serving users. CentML’s 2023 description, TechCrunch’s product account and the 2024 platform announcement outline these capabilities.
Training and inference are different optimization problems
Training
Training fits a model’s parameters and can require large, distributed GPU clusters. Better utilization or more efficient execution may reduce the time and compute needed for experimentation. The value depends on the particular model, hardware and training setup.
Rank #3

- Professional AI & Creator Workstation: AMD Radeon AI PRO R9700 GPU with 32GB GDDR6 is engineered for AI development, professional content creation, and compute-intensive workloads.
- Massive 32GB Memory Capacity: 32GB of GDDR6 memory on a 256-bit bus provides ample bandwidth for large AI models, 8K video editing, and complex 3D rendering.
- Advanced RDNA 4 with AI Accelerators: 64 Compute Units with 3rd Gen Ray Tracing and dedicated 2nd Gen AI Accelerators for groundbreaking AI performance and visual computing.
- Professional Blower Cooling: Efficient single blower design exhausts heat directly out of the chassis, ideal for multi-GPU workstation and server configurations.
- Enterprise-Grade Thermal Solution: Vapor chamber heatsink with industrial Honeywell PTM7950 thermal interface material ensures reliable cooling under sustained professional loads.
Inference
Inference runs a trained model to generate outputs for applications or users. Improvements can affect latency, throughput, per-request costs and GPU memory needs. Because inference workloads vary with traffic, batch size and response length, an optimization result for training should not be assumed to apply to inference, or vice versa.
Performance can change with model architecture, batch size, sequence length, numerical precision, memory limits, networking, compiler support and GPU generation. A team needs to validate results against its own workload rather than extrapolate from a different model or setup.
What CentML’s performance claims establish—and what they do not
CentML said its technology could accelerate training and inference by as much as 8×. It also reported an example in which it optimized Llama 2 to run 3× faster on Nvidia A10 GPUs while reducing cost by 60%. These are company-reported figures, not independently verified results in the cited material. The available descriptions do not establish a representative production outcome, whether the comparison was end-to-end, whether accuracy was held constant, or enough baseline detail to reproduce the results.
Rank #4
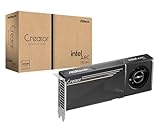
- System Compatibility Note: 2-slot card, 271x112x39mm, single 8-pin power, 200W TDP. Verify chassis clearance and PSU capacity before purchase.
- Dedicated Support: Please contact us directly through Amazon for any product questions or assistance you may require.
- 24GB GDDR6 on 192-Bit Bus: Massive 24GB memory with 456 GB/s bandwidth – ideal for LLMs, AI inference, 3D rendering, and generative design.
- Intel Xe2-HPG Architecture: Built on Intel's next-gen architecture with 20 Xe cores and 160 XMX engines for AI acceleration (197 INT8 TOPS).
- PCIe 5.0 Support: PCI Express 5.0 x16 interface for maximum bandwidth with the latest workstation platforms.
A large improvement may be possible when a particular workload has substantial inefficiency, but “up to” is not a typical-result guarantee. Buyers should ask what baseline was used, whether speed and cost were measured at equivalent quality and service targets, and whether the benefit persists on their model and traffic pattern. The figures are reported in CentML’s announcement and discussed by TechCrunch.
Why Google’s fund and Nvidia might be interested
The investment is consistent with a broader infrastructure thesis, though the cited announcements do not state each investor’s specific motivation. Google’s venture fund gains exposure to AI infrastructure software. Nvidia can benefit if better tooling makes its installed GPU base more productive and makes accelerated computing accessible to more projects. Lower deployment costs could also make new AI workloads economically viable, expanding demand for compute rather than simply reducing it.
Recommended Free Tools
There is a reasonable neutrality question when a GPU maker invests in optimization software: customers may want to know whether a platform works across accelerator types or favors one ecosystem. The investment alone is not evidence of improper influence or proof that CentML is limited to Nvidia hardware. Organizations should verify supported GPUs and frameworks directly.
Best Value

- PLEASE NOTE: Exporting an NVIDIA RTX Pro 6000 GPU outside the US requires strict adherence to the U.S. Export Administration Regulations (EAR) and issuance of an export license from the Bureau of Industry and Security (BIS). Compliance and Know Your Customer (KYC) screening may be required as a condition of order acceptance. [NVIDIA Blackwell Streaming Multiprocessor] The new SM features increased processing throughput, and new neural shaders that integrate neural networks inside of programmable shaders | DLSS 4: Multi Frame Generation ensures ultra-smooth frame pacing for lifelike simulations.
- [Double-Flow-Through Design] The RTX PRO 6000 Blackwell features a double-flow-through cooling design, optimizing efficiency and airflow to sustain peak performance under 600W power loads. | [5th Gen Tensor Cores] Deliver up to 3X the performance of the previous generation and support for FP4 precision for faster AI model processing times with reduced memory usage, enabling local fine-tuning of LLMs and generative AI | [4th Gen Ray Tracing Cores] Double the ray-triangle intersection rate of the previous generation to create photoreal, physically accurate scenes and immersive 3D designs with RTX Mega Geometry, which enables up to 100X more ray-traced triangles.
- [PCIe Gen 5] Support for PCIe Gen 5 provides double the bandwidth of PCIe Gen 4, improving data-transfer speeds from CPU memory and unlocking faster performance for data-intensive tasks like AI, data science, and 3D modeling. | [GDDR7 Memory] With 96 GB of GPU memory and 1.8 TB ps bandwidth, it can tackle massive 3D and AI projects, fine-tune AI models locally, explore large-scale VR environments, and drive larger multi-app workflows.
- [DisplayPort 2.1] Achieve unparalleled visual clarity and performance, driving high resolution displays at up to 8K at 240 Hz and 16K at 60 Hz. Increased bandwidth enables seamless multi-monitor setups while HDR and higher color depth support ensures superior color accuracy for precision work, such as video editing, 3D design, and live broadcasting.
- [Universal MIG] Divide a single RTX PRO 6000 Blackwell into multiple isolated instances, each with dedicated resources, allowing for concurrent execution of multiple workloads, optimized GPU utilization, and secure isolation of different applications or users. [WARRANTY] 3 YR Manufacturer's Warranty. Bulk OEM Packaging. Retail Packaging is NOT included.
Where optimization software may—or may not—help
Potentially good fit
- Your organization already has GPU access, but measured utilization or inference economics are poor.
- You have repeatable workloads that can be profiled and benchmarked.
- You need to compare GPU generations or deployment configurations before committing capacity.
- Your team can test compiler changes and confirm that performance gains do not harm model quality.
Not a substitute for
- Obtaining GPUs when no suitable capacity is available.
- Fixing a bottleneck that is primarily in networking, storage, data loading or CPU preprocessing.
- Hardware with a required memory capacity, interconnect or feature that alternatives lack.
- Workloads whose custom operators, irregularity or small scale make optimization incompatible or uneconomical.
Native tools from Nvidia and cloud providers may already be sufficient, and a managed service can be simpler to operate. Relevant comparisons include Nvidia AI Enterprise, Google Vertex AI, Amazon SageMaker and Microsoft Azure Machine Learning. For teams whose primary issue is obtaining dedicated GPU capacity rather than improving an existing deployment, CoreWeave represents a different kind of option. Databricks’ machine-learning platform is another comparison for organizations already invested in its ecosystem; MosaicML, cited as a peer in 2023 coverage, is no longer an independent startup following its acquisition by Databricks.
What the 2024 platform announcement added
In November 2024, CentML announced a platform with serverless endpoints, model optimization, GPU selection, infrastructure planning, autoscaling, traffic management and monitoring. The company described support for open-source and custom models and options involving private infrastructure or dedicated cloud deployment. The announcement also advertised $2.50 per million tokens for Llama 3.1 405B, called “Llama-405B” in the release, and claimed speeds up to twice as fast and costs 30% lower than unspecified market offerings.
Those price and performance figures are historical vendor claims published in November 2024, not confirmed current pricing or independently established results. They should not be used as a present-day budget assumption. The announcement does not, by itself, establish current availability, supported models, service levels or production uptime. See CentML’s November 2024 platform announcement.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →What to verify before evaluating CentML
- Which GPU, CUDA, driver, framework and model versions are supported?
- What is the benchmark baseline, and are speed, cost and accuracy compared on equivalent terms?
- Does the result hold for your own model, batch sizes, sequence lengths and traffic pattern?
- How are custom operators handled, and can the optimized model be exported to run elsewhere?
- Does customer data leave your environment? Can the platform run in a private VPC or on-premises?
- How is pricing calculated, and what costs arise from integration, testing and ongoing operations?
- What fallback is available if an optimization causes errors, performance regressions or quality changes?
- Does it support the accelerator types your organization uses, or only particular hardware ecosystems?
The available sources do not establish CentML’s current ownership, capitalization, headcount, customers, revenue, geographic footprint or present-day pricing. They also do not establish an Nvidia acquisition. The latest company product material cited here is the November 2024 platform announcement, which is not enough to confirm the company’s status or service terms in 2026.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.



